

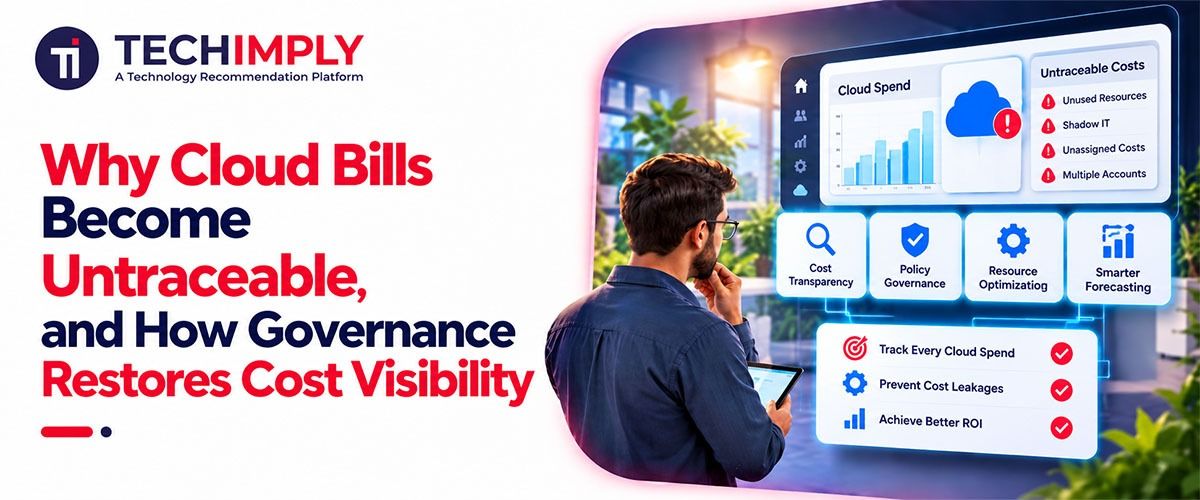
Unowned cloud resources produce untraceable infrastructure spend. Public cloud platforms generate variable usage records without inherent business context. Unassigned charges obscure financial accountability across engineering teams. Cloud cost governance restores line-item cost visibility. Mandatory metadata tags establish resource ownership boundaries. Automated budget guardrails prevent unexpected monthly invoice spikes.
Cloud financial operations frameworks within cloud environments match engineering choices to monetary measures. Teams spread across locations set up cloud resources bypassing core buying procedures. Ongoing check cycles keep long-duration infrastructure expense visibility clear.
TL;DR
- When variable usage events miss owner tags, account limits, and clear business groupings, cloud invoices turn into hard-to-follow documents.
- Implementing mandatory tags, isolating accounts, and using shared cost models within Kubernetes brings back detailed financial responsibility for each line item.
- Future Processing puts into place organized cloud governance structures that link the functional space found inside finance dashboards with those used by developer pipelines.
- Moving cost control left into Infrastructure as Code pipelines prevents overprovisioned resources from reaching production environments.
The Root Causes of Untraceable Cloud Spend
When monthly invoice lines lack assignment to distinct groups, apps, settings, or dev choices, untrackable cloud costs arise. Firms such as Future Processing frequently join forces with organizations to design robust framework strategies for cloud billing transparency governance. Advisory technical crews set up ordered allocation rules, clear tag levels, and automated compliance monitoring within intricate multi-cloud setups. Such organized direction aids engineering plus finance teams in building one joined working picture of all infra spending totals.
Variable utility- style billing and invoicing systems combine millions of tiny usage occurrences yet lack explanation regarding why such assets were allocated. Assets lacking ownership persist endlessly since no distinct person bears monetary duty for their duration. Loss builds up throughout cloud settings because of unclear obligation instead of deliberate error. Required data markers pinpoint asset proprietors, but tagging standards frequently suffer from severe tag drift across disparate engineering teams.
Tag drift happens when distinct units utilize mismatched key titles, differing case styles, or opposing figures for the very same functional groups. One expense hub could surface under several key forms throughout isolated project rollouts. Such variance blocks core invoicing systems from combining consumption into precise commercial perspectives.
Resource allocation efforts break down when organizations fail to update metadata as team structures change. Engineers frequently leave projects or change roles without transferring ownership records for running cloud assets. Unclaimed resources continue to bill monthly fees while central teams hesitate to terminate active workloads without confirmed operational context.
-
Granularity and Line-Item Export Volume
Cloud provider billing exports generate millions of distinct line items every month. Native billing exports record raw consumption metrics, including compute hours, API requests, and data egress bytes. These granular reports describe exact technical activity but omit logical business context.
Invoices default to grouping expenses by provider service types and regional availability zones. This basic operating framework does not link costs to items, traits, or inside client categories. There is no straightforward upfront allocation setting in place; thus, accounting units are unable to aggregate tiny fees into valuable financial statements.
The need for data transformation and complicated workflows to extract valuable information out of dense billing records is clear. As no automatic intake system is available, the periodic financial analysis will prove to be quite challenging. Overly complicated charging systems mask expense trends under the weight of technical complications.
-
Opaque Shared Infrastructure
Single root-level invoices encompass several workloads when using shared technical platforms. Resources get absorbed by container clusters that run on Kubernetes, multi-tenant database clusters, shared network gateways, and data engineering pipelines from many internal applications. The provider invoices charge for these parts at the cluster or root organization level.
Enterprise support plans and organization-wide licensing costs create comparable issues regarding credit assignment. Lacking a distinct division method, common resources show up as one solid, unnamed cost section inside business invoices. Teams using these systems skip money responsibility if shared system spending stays grouped.
-
Delayed Financial Feedback Loops
Engineering speed frequently runs completely off-beat from standard monthly finance check-in periods. Development teams push code, launch testing grids, and automatically resize live servers within moments, given strict shipping limits. Practitioners concentrate mainly on uptime, release rate, and average repair duration.
Financial feedback typically reaches engineering leads roughly thirty days after invoice periods close. When finance detects an unanticipated rise, the relevant technical background has already slipped out of sight. Late responses stop coders from connecting particular design decisions with their direct monetary results.
Uncoordinated acceleration creates systemic bottlenecks across development and finance teams. As Konrad Bałys, Head of Engineering at Future Processing, noted in their AI transformation case study: "When one part of the process speeds up, a new wall appears somewhere else. One person being faster gives us nothing. The whole team has to be faster, in every phase."
Fast deployment lines lacking synced money tracking let unchecked building prices pile up quickly later on. Setting live price response matches build speed with ongoing cash rules.
Building Cost Accountability: How Governance Restores Visibility
Cloud governance brings back cost visibility by requiring tags to be applied, setting up clear account limits, and sending automatic warnings when budgets hit set points on every way resources get created. Groups reach financial responsibility by using organized systems, non-stop monitoring, and common work habits that everyone follows.
-
Ownership, Mandatory Tagging, and Account Boundaries
Clear ownership frameworks guarantee that all active resources connect straight to a specific group or division within the company. Based on guidance from the FinOps Foundation, successful handling of cloud expenses demands that people accept full accountability for how they utilize the system. Required tagging fields such as owner, enviroment, and cost center supply the necessary data details required to sort out spending related to hardware setup.
Cost isolation receives another structural layer from account boundaries, which function apart from tag coverage. Billing unit allocation in the form of workloads managed via AWS Organizations accounts, Azure management groups, or Google Cloud projects creates separate billing zones. Cost allocation tags defined by users need to be enabled in the billing console to show up in the cost report generated by Amazon Web Services.
Making sure tags follow rules needs automatic checking systems that look over deployment manifest files all the time. Resources that break rules set off alert messages or isolation steps that limit entry until needed data labels get added. Tight rule systems stop infrastructure without tags from moving into live areas without anyone noticing.
-
Cost Allocation, Showback, and Shared Infrastructure
Expense allocation will distribute infrastructure costs among user groups via detailed usage reports and cost allocation guidelines. The showback model will provide assigned values to developers so that they know their spending limit, while the chargeback model will debit money from organizational accounts. Each approach needs precise distribution structures to stop leftover general costs from building up at the top payment tier.
When shared assets exist without distinct allocation guidelines, serious problems regarding credit assignment arise. Cloud billing statements frequently list expenses for common Kubernetes environments, databases serving multiple tenants, processing workflows, and corporate assistance charges as one broad entry lacking specific tags. Firms address these issues by dividing the total cost of such groups based on namespace boundaries, pod resource requests, and measured usage figures.
Broad data governance activities match technical designs straight to wider accounting rules throughout company units. Consulting teams check current setup maps to remove double billing and smooth out cloud bill combining. One clear view lets top bosses check real per-unit profits across separate software groups.
|
Governance Component |
Primary Operational Role |
Cost Visibility Outcome |
|
Mandatory Tagging |
Attaches metadata (owner, environment, cost center) to resources |
Assigns line-item spend to explicit teams and products |
|
Account Boundaries |
Isolates workloads using AWS accounts, Azure subscriptions, or GCP projects |
Creates automated billing perimeters independent of tags |
|
Shared Cost Allocation |
Splits Kubernetes clusters and support fees by namespace and pod usage |
Eliminates central unallocated overhead blocks on invoices |
|
Budget Threshold Alerts |
Triggers notifications at 50%, 80%, and 100% spend milestones |
Informs resource owners of overruns before month-end |
-
Budgets, Anomaly Detection, and Financial Controls
Budget alerts will notify resource owners about possible expenditure increases before the end of the monthly billing cycle. Budget spend set to 50%, 80%, and 100% will result in automatic alert notifications for designated personnel. These alerts should be sent to developers and not monitored email groups to allow swift action.
Learning-based native and third-party anomaly detection systems will examine historical usage data to find unusual spending increases in a matter of hours. Algorithms will factor in expected seasonality and growth trajectory and distinguish planned scale-ups from misconfiguration. It will allow fast detection of isolated technical problems resulting in unwanted charges.
Defining exact limits for spotting anomalies stops fatigue from hitting engineering staff running operations. Alerting tools tune how sensitive they get using past wild swings in numbers that are specific to each place. Good warnings let workers look into strange uses of resources before money goes up very fast indeed.
Moving Cost Control Left into Engineering Workflows
Moving cost governance left integrates financial feedback directly into early infrastructure design and continuous deployment pipelines. Transferring cost evaluations into development workflows prevents overprovisioned architecture from reaching production environments.
-
Policy as Code and Automated Guardrails
Policy as code engines evaluate infrastructure changes before deployment occurs. Tools such as the Open Policy Agent examine the infrastructure to ensure that code bundles remain continuously integrated within the pipeline. Policy rules require that valuable metrics highlight isolated instances, external locations, or missing metadata tags before a resource is created.
Automated verification is assigned to distinct enforcement tiers based on the level of risk each tier poses. The policy system, by recommending that it display maximum costs, requires a sign-off from the administrator, or completely halts non-compliant rollouts. It prevents unauthorized modifications from being pulled into requests, eliminating the need for a later cleanup.
The cost-calculation tool, when integrated directly into version-control systems, allows programmers to view response times at any moment by tracking request pulls. The technical team responsible for monthly forecasting reviews changes against the code, noting differences from previous versions when adding structural modifications. The economic benefits are clear in supporting development teams by selecting the most cost-effective server type in advance.
-
Lifecycle Automation and Off-Hours Scheduling
Production systems that don't run frequently don't stop even when no operators touch them for days or weeks. Developers handling application lifecycle management have set up auto-shutdowns for VMs and containers that aren't marked as production after work ends. By putting these tags in place, they decide to charge for non-production areas in computing costs without delay, as quickly as the devs move.
The rules for the stored life cycles regularly wipe out the world's storage clutter, unaffected objects, old snapshots, and logs whose time has passed. Auto-expiration days tied to a short sandbox period ensure the full removal of resources once the tasks are completed. The automated cleanup stops leftover items from builds and causes a silent ticket to be issued each month.
Long-term experimental projects require different approaches to automate resource allocation rules. They seek a short time frame using simple online tools, since certain experiments have fixed time limits. Tackling isolation preserves the worker's high speed but keeps the total team expenditure tightly constrained.
Practical Steps to Explain and Contain Your Cloud Spend
Once the mandate is received, the designated infrastructure expenditure requires a phased action schedule. Companies build clear cost profiles and opinions, methodically proceeding through the main diagnostic steps.
Rapid Diagnostic Sequence
Fundamental societies can establish cost clarity by implementing a five-day work schedule.
- Activate Native Tools: Convert to the cloud, built-in review coverage, broad alerting tools, and anomaly-spotting utilities.
- Configure Threshold Alerts: Configure real-time notifications for spending limits, with 50, 80, and 100 percent monthly weighting.
- Enforce Ownership Metadata: Require an owner and establish identifiers on every running resource, which segregates unclaimed tags until they are publicly reclaimed.
- Assign Top Line-Item Owners: Ensure all the resources that are currently used have an owner and corresponding identifiers. Do not use any unassigned tags until there is a public assumption of ownership.
- Schedule Off-Hours Shutdowns: Find major computing blocks and set up shifts for every non-production scenario. Fast and practical training leads to quick wins, revealing significant cost-saving opportunities.
Early success confirms that operational policies dictate spending and ensure standardization of finances and coding processes. The initial cleanup removed unnecessary waste, which is essential for the future agile approach to managing expenses over time.
Establishing Continuous Review Cadences
If teams that oversee cost management focus solely on individual events, they will break the machine's governance. Leaders in finance, FinOps, and engineering need to review the most frequent meetings to jointly inspect cost distribution documentation. By sharing common information in these joint meetings, they ensure that both technical teams and various business divisions stay aligned around cost patterns.
Continuous governance identifies the right action to take based on normal metrics for machine instances, such as latency, availability, and error rates. Evaluating unit cost per transaction or active user, connecting to the cloud and spending directly on the entire resource expansion. Review cycle exercises help ensure long-term cost efficiency in operating cloud-native applications.
Care is taken to prioritize specific key performance indicators so that the management system can remain effective over many years. Metrics such as the percentage of money allocated to owners, tag-following rates, and total idle capacity are monitored. Stable logging shows movements toward optimal usage.